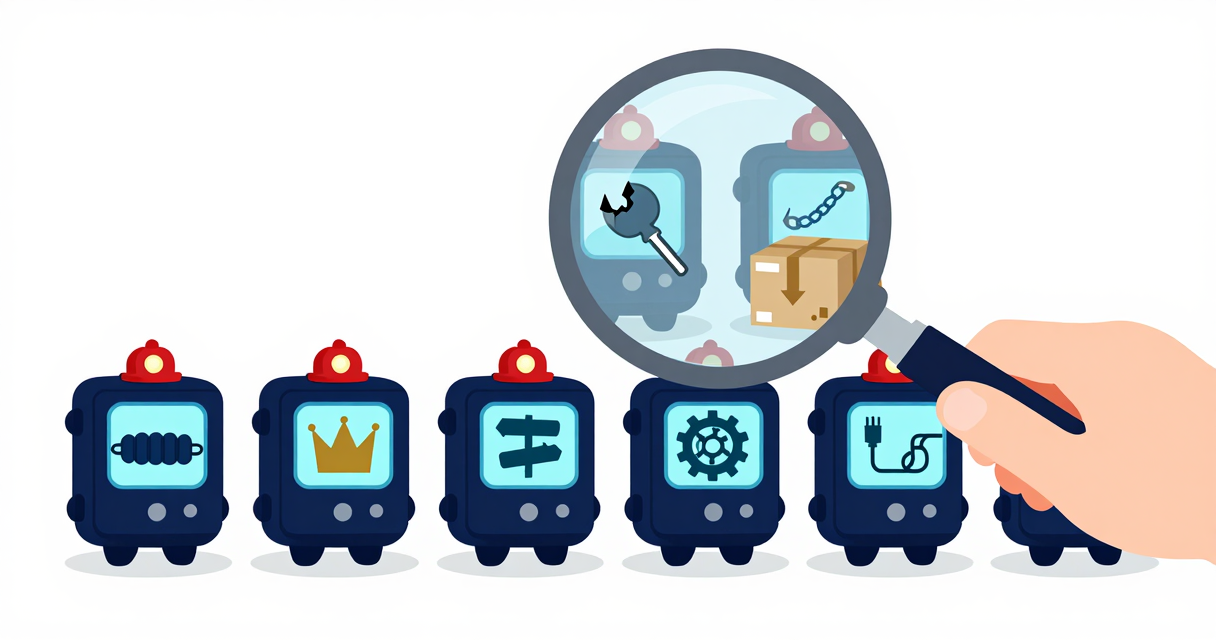
A platform engineer recently described walking into their RKE2 clusters and finding 13 crash-looping pods across 8 namespaces, with CrashLoopBackOff, ImagePullBackOff and ContainerCreating everywhere. It looked like one big outage. It was seven unrelated problems wearing the same status line.
The status column is shared. The causes are not. This is one engineer's account, so treat the specifics as illustrative.
Seven causes behind one status line
The seven causes in that report were: volumes full because orphaned replication slots stopped Postgres from cleaning up its write-ahead log; versioned images that had moved registries while Helm charts still pointed at the old location; registry pull secrets in several namespaces that all depended on one personal access token, which then expired; an HA Postgres cluster that lost its leader; storage driver credentials that broke during a cloud tenant migration; a wrong message-queue hostname; and a broken build that slipped past CI.
Why fixing pods in order fails
If you fix pods in the order they appear, you burn the first hour on symptoms. Three namespaces may fail on one expired token. A database may be down because its volume is full, and the pods that depend on it only look broken. Meanwhile the one change that is truly urgent, the bad build, sits at row nine.
The six-step triage pipeline
Solution label: Proposed architecture (a triage method, not something we ran against that cluster).
- 01
Take one snapshot first
Capture the non-running pods and the most recent events before changing anything.
- 02
Classify every pod by its first-order signature, not its status
Exit 137 with reason OOMKilled points to memory. ImagePullBackOff points to an image or pull secret. FailedMount points to storage. FailedScheduling points to capacity. A fast exit with a config or connection error on the last log line points to config or a dependency.
- 03
Group by shared dependency
Same Secret, same PVC, same image reference, same node, same StorageClass. One finding per cause, not one per pod. Thirteen pods usually collapse to a handful of causes.
- 04
Rank by blast radius and what is cheapest to undo
Rolling back one deployment is cheap to undo. A credential change is not.
- 05
Pick an action tier for each cause
Safe and undoable (can be automatic), changes cost or running state (one human approval), or needs a design decision (human only).
- 06
Re-run the exact check that found the problem
A pod that stays Running for five minutes is evidence. A green status one second after the change is not.

kubectl get pods -A --field-selector=status.phase!=Running
kubectl get events -A --sort-by=.lastTimestamp | tail -50
kubectl logs <pod> --previous
What the seven causes look like in the pipeline
- Full volumes from a stuck replication slot. Expanding the volume needs one approval because it costs money, and it only buys time. The real fix, dropping or advancing the stale slot, is a database decision for a person. Alert on slot lag so it never reaches 100 percent again.
- Images that moved. The fix is a change in Git (the chart or values file), not in the cluster. Treat it as a reviewed change.
- One personal token behind many pull secrets. A person has to renew it. The durable fix is to give the registry credential a service identity and sync it from your secret store, so a rotation does not break a dozen namespaces.
- Database lost its leader. Database-level recovery, human only.
- Storage credentials invalid after a migration. A person rotates the credential. Early detection of failed mounts shortens the outage.
- Wrong message-queue hostname. A config change, proposed and reviewed.
- Broken build. Roll back to the last good revision once a person approves, then fix forward.
Credential changes, slot drops, volume expansion and rollbacks all change production. Each needs the approval tier above, and none should be applied just because a status looks red.
Where Srenix fits
Srenix is an autonomous AI SRE that runs inside your cluster. It is in Beta, and we are working with Design Partners now. For this incident shape it can take on the first hour of triage.
It detects per cause, not per pod. Its Kubernetes probes cover crash loops, pending pods, failed mounts, PVCs, node pressure and Postgres on CloudNativePG, and each finding is a Kubernetes resource you can read with kubectl get driftreports. It diagnoses with plain rules first and uses a model you host as the fallback, so cluster data and prompts stay inside your perimeter.
It fixes only what your policy allows. A missing key that your secret store already holds can be re-synced without Srenix ever reading the secret value. A full volume is grown after one tap in Slack. A bad deploy gets a proposed rollback that runs only after you approve it. Every automatic action passes a seven-check gate (autonomy on, breaker closed, proposal present, action kind allowed, namespace not protected, rollback present, confidence at least 0.95) and is followed by the same detection to prove the problem is gone.
What Srenix will not do: mint a new access token, rewrite your chart image path on its own, or repair a database timeline split. Those arrive as clearly explained findings with a proposed next step, so the engineer on call starts at the cause instead of at thirteen red pods. Everything is written to a signed, hash-chained audit trail.
Tradeoffs and failure modes
- Over-grouping. Two failures can share a dependency and still have different causes; confirm with the first-order signature before acting on a group.
- Triage is not a fix. Classification tells you who acts and how risky it is; the repairs still need people.
- Shared causes hide a worse one. A full volume may be the visible problem while a stuck slot keeps refilling it.
- Time pressure. Under stress, teams skip the snapshot. Automate it.
How to validate
Acceptance criteria are targets, not measured results:
- A simulated multi-cause incident collapses to one finding per cause.
- Each finding carries an action tier and a proposed next step.
- After each approved fix, the original check passes and stays green for five minutes.
- The audit record shows who approved what.
Test plan: in a throwaway cluster, inject four faults at once (an expired pull secret, a full volume, a wrong hostname and a bad image tag), run the pipeline, and time how long it takes to produce a ranked list of causes.
The taking point
Triage by cause, not by status: group pods by shared dependency, rank by blast radius and reversibility, and verify each fix with the check that found it. If your last bad night looked like this one, you can ask for a walkthrough on your own cluster at reliora.ai.
